Home / Research / Text Embedding API Pricing Statistics
Text Embedding API Pricing Statistics: September 2026
 By Darin ten Bruggencate, Founder, AI Industry Reviews · September 9, 2026
Search tools and AI assistants that answer questions from a company's own files need a way to find the passages that match a question. They do it with text embeddings, which turn each document and each query into a list of numbers so software can tell which passages are close in meaning. Several AI companies sell this as a service, each at its own rate, so we compared what the same amount of text costs with each one.
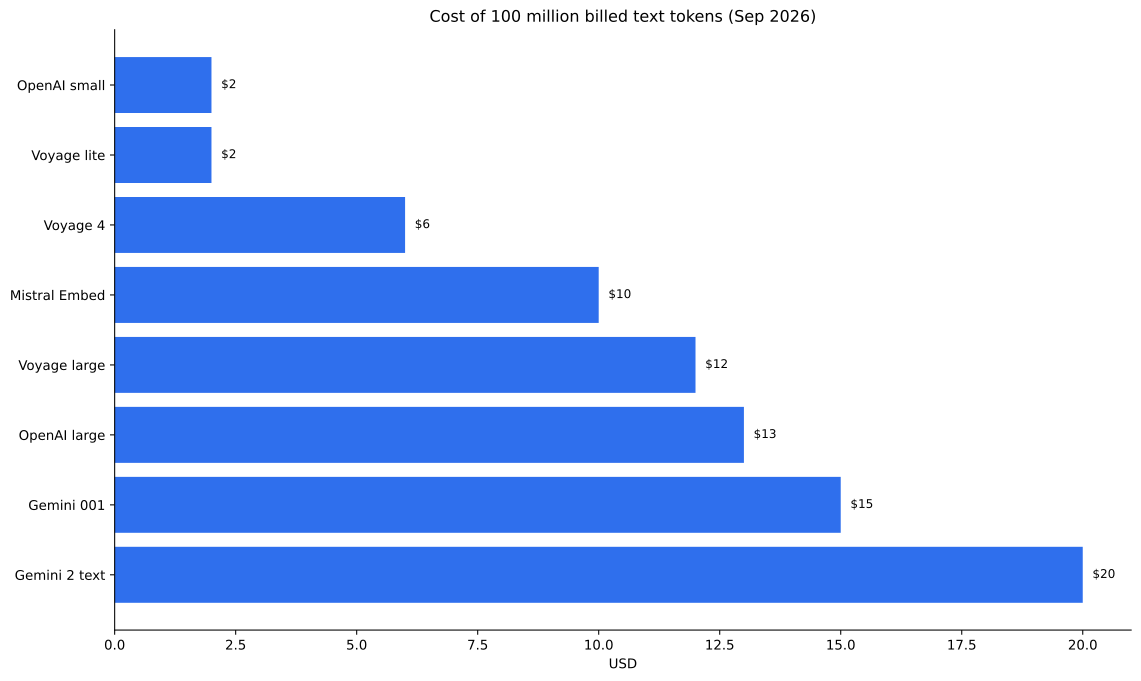
Our analysts priced eight text embedding models from OpenAI, Google, Voyage AI and Mistral AI. We took each vendor's published standard rate on September 9, 2026. We applied one common volume of 100 million billed input tokens with the same arithmetic for every model. The cost of 100 million billed tokens runs from $2 to $20, with a median of $11.
In the following sections, we compare the cost by model, identify the cheapest model from each provider, and explain why an actual bill can differ.
On this page: Cost by model · Cheapest by provider · Actual bill · Methodology · Sources
What 100 Million Billed Tokens Cost by Model
Inside the sample, the cheapest rate is $0.02 for each million input tokens, on the small model from OpenAI and the lite model from Voyage. Google's text input price for Gemini Embedding 2 is the highest, at $0.20. Each amount takes the published rate for that model and applies it across all 100 million tokens.
API Prices for Text Embedding Models, September 2026
Scroll sideways to see every column.
| Provider | Model ID | Price per million input tokens | Cost for 100 million tokens (calculated) |
|---|---|---|---|
| OpenAI | text-embedding-3-small | $0.02 | $2 |
| Voyage AI | voyage-4-lite | $0.02 | $2 |
| Voyage AI | voyage-4 | $0.06 | $6 |
| Mistral AI | mistral-embed-2312 | $0.10 | $10 |
| Voyage AI | voyage-4-large | $0.12 | $12 |
| OpenAI | text-embedding-3-large | $0.13 | $13 |
gemini-embedding-001 | $0.15 | $15 | |
gemini-embedding-2 (text input) | $0.20 | $20 |
Every price is in US dollars. Vendors supplied the price column, and we calculated the last column. Mistral's API guide also lists the alias mistral-embed.
Insights
- At a fixed token volume, the most expensive sampled model costs 10x the cheapest: $20 against $2 on 100 million billed tokens.
- In this scenario, four models from the eight come in at $10 or under.
- Embedding costs are small at moderate volumes. The gap between the priciest and cheapest sampled model grows to $180 at one billion tokens, so it matters mainly for very large indexes.
The 10x figure covers only the rates listed in this sample, and it says nothing about which model gives the best search results.
Cheapest Model in the Sample by Provider
Voyage has three rows in the full table, OpenAI and Google have two each, and Mistral has one. Counting every model would give providers with more models more weight, so we kept only the sampled model with the lowest price for each provider.
Lowest Embedding Price Sampled for Each Provider, September 2026
Scroll sideways to see every column.
| Provider | Lowest-priced sampled model | Cost for 100 million billed tokens |
|---|---|---|
| OpenAI | text-embedding-3-small | $2 |
| Voyage AI | voyage-4-lite | $2 |
| Mistral AI | mistral-embed-2312 | $10 |
gemini-embedding-001 | $15 |
Insights
- After sorting, $2 and $10 are the two central values among the four provider costs, and $6, their midpoint, is the median.
- Here, the top provider cost is 7.5x the bottom one, $15 against $2.
- OpenAI and Voyage AI share the lowest rate among the providers, $0.02 per million input tokens.
Both medians describe only this sample, and we did not estimate what a typical business pays. Each provider row is the lowest-priced model we sampled, and that provider may sell a cheaper offer than the one we kept.
Why the Actual Bill Can Differ
Voyage gives the included models a free allowance of 200 million tokens. Our calculation uses the paid rate only after that allowance is spent. Someone still inside the free allowance might be charged less for an equal number of tokens. Paid-rate comparisons here also leave out the free tier Google offers.
Gemini Embedding 2 takes several kinds of input, and the table's figure is its text input price. Images and audio are out of the comparison, as are video and PDFs.
Tokenizers differ, so one collection of documents can yield different token counts from one provider to another. How many tokens a system processes can change if chunks overlap or the corpus is reindexed, and query embeddings can change it as well. A team choosing its embedding model should measure retrieval quality on documents it owns, and should also factor in response time and the cost of vector storage.
What Text Embedding API Pricing Means for 2027 and Beyond
Turning text into embeddings for search and recommendation is cheap for most companies. Costs only become meaningful at very large scale, and the bigger expense is having to redo the whole collection when switching to a new model.
Because prices are low, model choice comes down to how well a model finds the right results and how hard it is to switch later. A cheaper model that forces a full re-index can end up costing more than it saves.
So if you are picking an embedding model, test search quality on your own data and count the cost of re-indexing before you switch.
Data Collection and Methodology
Prices were gathered on September 9, 2026 from the model pages and the official pricing page of every vendor. Sources lists every page, and so does the CSV download. The sample has OpenAI's small and large text-embedding-3 models, both stable Gemini embedding models from Google, Voyage's three current text models in the general-purpose line, and Mistral Embed. This declared sample covers four providers and stops short of a full list of embedding APIs.
Exclusions cover releases still in preview, alternatives that are older and sit beyond the families already listed, specialized models for code and for industry use, contextualized chunk endpoints, prices quoted by resellers, and self-hosted models. All calculations use text requests on the standard paid plan. Free credits, batch discounts, terms for enterprise buyers and costs of infrastructure remain outside it.
Per model, price for a million input tokens was multiplied by 100. The volume of 100 million tokens is split across requests that stay inside the model's limits. When comparing providers, we kept the sampled model with the lowest price from each one and took the median across them.
No retrieval benchmark was run, and no 100-million-token job was submitted. Prices here are vendor observations, while the costs at one shared volume, the medians and the spreads are figures we calculated.
Sources
- OpenAI, text-embedding-3-small. Price and ID for the standard embedding.
- OpenAI, text-embedding-3-large. Price and ID for the standard embedding.
- Google, Gemini Developer API pricing. Standard rates on the paid tier for Gemini Embedding, also for Gemini Embedding 2.
- Voyage AI, Pricing. Current text embedding rates and free-token allowances.
- Mistral AI, Mistral Embed. Price of the model and the versioned ID.
- Google, Gemini Embedding 001 and Gemini Embedding 2. Stable model status and supported input types.
- Voyage AI, Text embeddings. The current family of general-purpose models.
- Mistral AI, Embeddings and Embeddings API. A general-purpose model for text, plus the API alias.
Cite the analysis this way: AI Industry Reviews, "Text Embedding API Pricing Statistics: September 2026," with prices checked on September 9, 2026. Keep the billing assumptions beside any cost figure you quote.