Home / Research / AI Token Pricing Comparison
AI Token Pricing Comparison: September 2026
 By Darin ten Bruggencate, Founder, AI Industry Reviews · September 1, 2026
AI models are priced per million tokens, the small chunks of text a model reads and writes. But a model's published price doesn't show how many tokens it uses to finish a task, which we call token burn. So two models with the same price can produce very different bills, and we looked at how far apart they land.
Our analysts ran a 240-task suite on four models: GPT-6 Astra, Claude Fable 5.1, Gemini 3.1 Pro and Grok 4.6. Each ran at default reasoning through its vendor's first-party API. We logged every input, cached input, output and reasoning token and priced it on published rates as of September 1, 2026. Two models at the same $50.00 per million output differ by 22 percent on a long document and by 63 percent across a coding session.
In the following sections, we compare published prices with tokens used per task, then show session costs, cost per 1,000 runs by workload and monthly spend per developer.
Published token prices
The table lists each model's published rate per million tokens, its context window, and its long-context rate. Google and xAI set the long-context threshold at 200,000 tokens and bill the higher rate against every token in the request once a prompt reaches that line. OpenAI publishes long-context rates without a published threshold; this study applied the same 200,000-token line.
| Model | Vendor | Input | Cached input | Output | Context window | Long-context rate |
|---|---|---|---|---|---|---|
| GPT-6 Astra | OpenAI | $10.00 | $1.00 | $50.00 | 1.05M | 2x input, 1.5x output |
| Claude Fable 5.1 | Anthropic | $10.00 | $0.25 | $50.00 | 1M | None, flat to 1M |
| Gemini 3.1 Pro | $2.00 | $0.20 | $12.00 | 1M | $4.00 in, $18.00 out | |
| Grok 4.6 | xAI | $2.00 | $0.50 | $6.00 | 500K | $4.00 in, $12.00 out |
Insights
- GPT-6 Astra and Claude Fable 5.1 match on input at $10.00, output at $50.00, and cache writes at $12.50 per million, and differ on cache-hit reads.
- Cached input is the widest published gap: Claude Fable 5.1 at 2.5 percent of base input, Grok 4.6 at 25 percent.
- A team that reuses context should price its own cache hit rate before choosing, because the cheapest model can change once caching is counted.
Token consumption per task
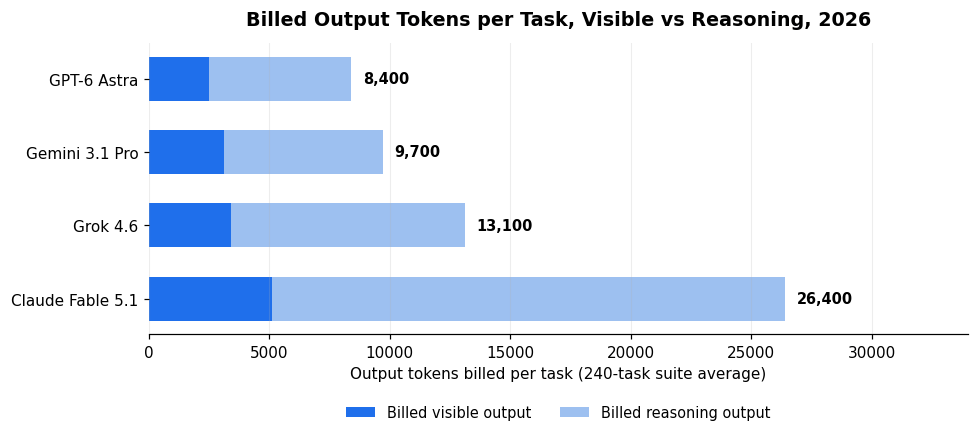
The rate card sets the price of a token, and the task sets how many tokens are billed. The table reports average output per task across the 240-task suite, split into visible output and billed reasoning, with a burn multiple indexed to GPT-6 Astra at 1.00x.
| Model | Visible output tokens | Reasoning output tokens | Total billed output | Reasoning share | Burn multiple |
|---|---|---|---|---|---|
| GPT-6 Astra | 2,500 | 5,900 | 8,400 | 70.2% | 1.00x |
| Gemini 3.1 Pro | 3,100 | 6,600 | 9,700 | 68.0% | 1.15x |
| Grok 4.6 | 3,400 | 9,700 | 13,100 | 74.0% | 1.56x |
| Claude Fable 5.1 | 5,100 | 21,300 | 26,400 | 80.7% | 3.14x |
Insights
- Reasoning is 68.0 to 80.7 percent of billed output.
- Claude Fable 5.1 spends 3.14x the output tokens of GPT-6 Astra at the same $50.00 per million, so comparable finished work lands at an effective $157.14 per million.
- Because reasoning tokens make up most of the output bill, buyers should compare cost per finished task.
Cumulative session cost across a 50-turn agentic run
Agentic runs resend accumulated working context as input on each turn. The table tracks cumulative spend across a 50-turn coding session of 1,030,500 input tokens, with a 72 percent prefix cache hit from the third turn. OpenAI and Anthropic bill cache writes above base input, and those writes are priced in. Google and xAI publish no separate cache-write line.
| Turn | GPT-6 Astra | Claude Fable 5.1 | Gemini 3.1 Pro | Grok 4.6 |
|---|---|---|---|---|
| 1 | $0.09 | $0.18 | $0.02 | $0.02 |
| 5 | $0.40 | $0.82 | $0.09 | $0.08 |
| 10 | $0.78 | $1.60 | $0.18 | $0.16 |
| 15 | $1.23 | $2.45 | $0.28 | $0.26 |
| 20 | $1.72 | $3.33 | $0.40 | $0.37 |
| 25 | $2.28 | $4.27 | $0.52 | $0.50 |
| 30 | $2.91 | $5.28 | $0.65 | $0.64 |
| 35 | $3.58 | $6.31 | $0.80 | $0.79 |
| 40 | $4.32 | $7.43 | $0.95 | $0.96 |
| 45 | $5.12 | $8.57 | $1.12 | $1.14 |
| 50 | $5.97 | $9.75 | $1.30 | $1.34 |
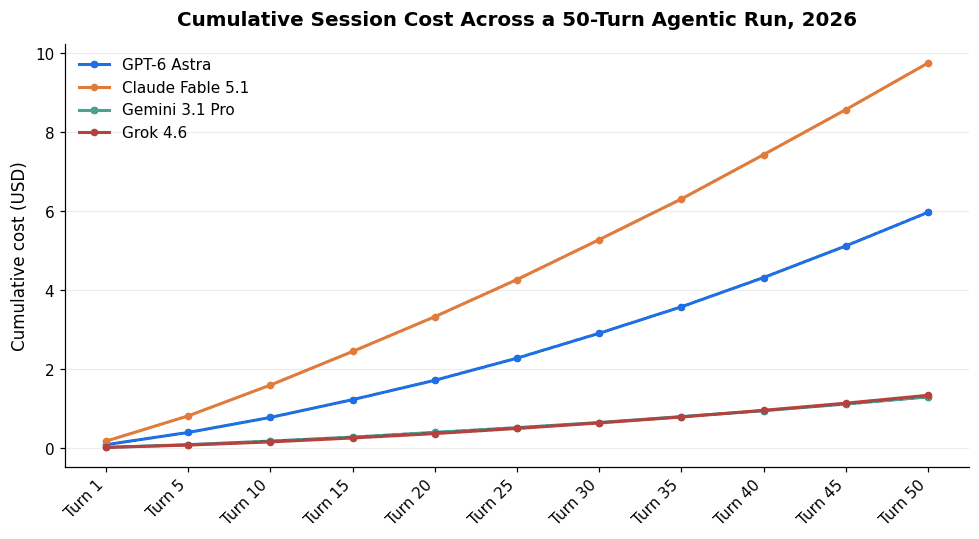
The chart plots the same figures. The four session totals separate on the first turn and remain apart through turn 50. By turn 10 the spread is $1.44, and by turn 50 it is $8.45, on a session that produced the same work in every case. Input grows from about 5,400 tokens on turn 1 to about 35,800 on turn 50. Caching reduces the input side of the bill and leaves per-turn output burn as the larger remaining variable. Gemini 3.1 Pro and Grok 4.6 stay within four cents for the run. A caching-disabled control on the same session raised session totals 71 to 106 percent.
Effective cost per 1,000 runs by workload
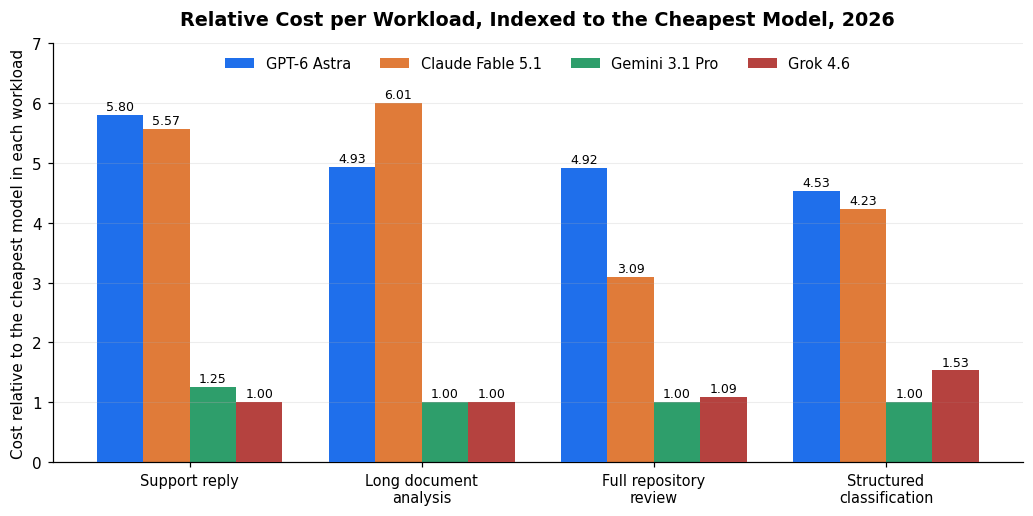
Rate and burn combine differently by the shape of the job. The table prices four workloads at 1,000 runs each, with the task held constant across models. The customer support reply and structured classification rows ran with reasoning disabled, so output length matches and only the rate card varies. Structured classification assumes batch wherever the vendor offers it.
| Workload | Input tokens per run | GPT-6 Astra | Claude Fable 5.1 | Gemini 3.1 Pro | Grok 4.6 |
|---|---|---|---|---|---|
| Customer support reply | 2,400 | $24.72 | $23.73 | $5.30 | $4.26 |
| Long document analysis | 120,000 | $1,023.60 | $1,248.60 | $207.79 | $208.01 |
| Full repository review | 340,000 | $4,540.50 | $2,851.25 | $922.69 | $1,003.18 |
| Structured classification | 1,800 | $8.00 | $7.46 | $1.76 | $2.70 |
Insights
- Ranking changes by workload. On jobs under 200,000 tokens, GPT-6 Astra is the cheaper of the two premium models. Above that line, OpenAI's long-context rates (2x input, 1.5x output) make it the more expensive, and Anthropic stays flat.
- Full repository review puts Claude Fable 5.1 37.2 percent below GPT-6 Astra on the same 340,000-token job.
- A team with mixed workloads can price each job type separately and may find a different model cheapest for each.
Monthly spend per developer
The figures below are monthly API spend per developer across 34 engineering teams, each on a single primary model, with the share of that spend from re-sent context and from system prompts and tools.
| Primary model | Median | 75th percentile | 90th percentile | Share from re-sent context | Share from system prompts and tools |
|---|---|---|---|---|---|
| GPT-6 Astra | $1,180 | $2,310 | $3,640 | 61% | 24% |
| Claude Fable 5.1 | $2,340 | $4,180 | $6,920 | 58% | 27% |
| Gemini 3.1 Pro | $395 | $810 | $1,465 | 66% | 21% |
| Grok 4.6 | $310 | $645 | $1,190 | 69% | 19% |
Insights
- The spread between the lowest and highest median is 7.5x, narrower than the 8.3x spread in published output rates.
- Re-sent context is 58 to 69 percent of every bill.
- Heavy users pay 3.0 to 3.8 times the median developer.
Conclusion
The price a model provider publishes is only a starting point for what a developer pays. How much the model reasons, whether repeated prompts are cached and how long the inputs run all change the monthly bill, often more than the published rate does.
The cheapest model on paper is not always the cheapest in practice, since the ranking changed from one workload to the next in our tests. Teams that test on their own tasks see costs that a rate card cannot show.
So if you are choosing a model for your team, run your own typical tasks on each option and compare the actual bills before you commit.
Data Collection and Methodology
| Layer | What it measures | Measurement scope |
|---|---|---|
| Published price | Price per million tokens on the published rate card for input, cached input, output, and long-context | First-party API rate cards as of September 1, 2026; standard synchronous unless a table says otherwise |
| Token burn | Visible output, billed reasoning, and total billed output per task | 240-task suite split evenly across agentic coding, long-document analysis, multi-step research, and structured extraction |
| Session cost | Cumulative spend across a multi-turn agentic coding run | 50-turn session of 1,030,500 input tokens with 72 percent prefix cache hit from the third turn |
| Workload cost | Cost of 1,000 executions of a defined production job | Four workloads at 1,000 runs |
| Monthly spend | Monthly API spend per developer, including the share from re-sent context and from system prompts and tools | 34 engineering teams on one primary model |
Published price is the rate. Token burn is the quantity billed to finish a task. Session cost, workload cost, and monthly spend apply both figures to larger units of work.
Sources
- Frontier Model Token Economics Study. AIR Research Team. September 2026. Houston, TX.
- OpenAI, API Pricing. September 2026. San Francisco, California. https://developers.openai.com/api/docs/pricing
- Anthropic, Pricing. September 2026. San Francisco, California. https://platform.claude.com/docs/en/about-claude/pricing
- Google, Gemini Developer API Pricing. September 2026. Mountain View, California. https://ai.google.dev/gemini-api/docs/pricing
- xAI, Models and Pricing. September 2026. Palo Alto, California. https://docs.x.ai/docs/pricing
- Artificial Analysis, Independent Analysis of AI Models. September 2026. Sydney, Australia. https://artificialanalysis.ai/models